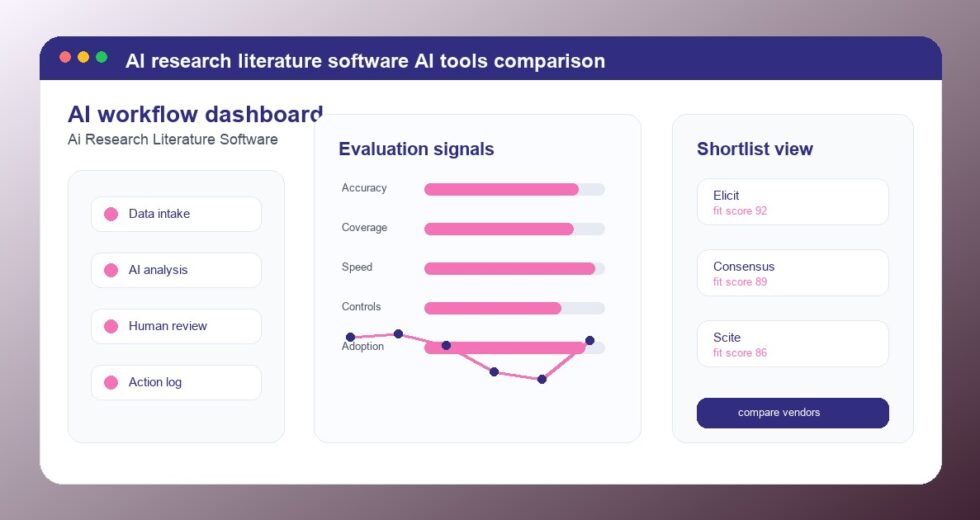
This best overall shortlist compares Elicit, Consensus, and Scite for teams evaluating AI research literature software. The three tools are not interchangeable. Each may be strong for a different operating model, integration requirement, data maturity level, or rollout style.
For researchers, students, and knowledge workers, the right decision should start with the workflow: literature search, citation context, and evidence synthesis. A tool that looks impressive in a demo may be the wrong fit if it cannot connect to existing systems, handle edge cases, or provide the audit trail your team needs.
Short answer
- Choose Elicit if its workflow depth matches your highest-priority AI research literature software use case.
- Choose Consensus if its implementation model, integrations, or data approach fits researchers, students, and knowledge workers better.
- Choose Scite if it offers the strongest match for literature search, citation context, and evidence synthesis, rollout needs, or reporting expectations.
- Run a AI research literature software pilot before making a long-term buying decision.
Comparison table
| Tool | Likely best fit | What to validate | Risk to check |
|---|---|---|---|
| Elicit | Teams prioritizing literature search, citation context, and evidence synthesis | Integration depth and real-case performance | Over-reliance on polished demo examples |
| Consensus | researchers, students, and knowledge workers with specific process constraints | Security, data controls, and workflow ownership | Implementation complexity |
| Scite | Teams comparing multiple approaches to AI research literature software | Reporting, user adoption, and support model | Unclear ROI measurement |
Elicit: where it may fit best
Elicit belongs on the shortlist when your team wants AI support for literature search, citation context, and evidence synthesis and prefers a focused product over a generic AI assistant. The best reason to evaluate Elicit is not simply that it uses AI, but that it may align with the roles, systems, and repeatable decisions inside AI research literature software.
- Pilot fit: use Elicit on a real literature search, citation context, and evidence synthesis process with normal and edge-case examples.
- Data fit: confirm what AI research literature software sources Elicit needs and how they are governed.
- User fit: test whether researchers, students, and knowledge workers can understand, edit, and trust Elicit output.
- Commercial fit: ask how Elicit pricing changes as literature search, citation context, and evidence synthesis usage expands.
Consensus: where it may fit best
Consensus belongs on the shortlist when your team wants AI support for literature search, citation context, and evidence synthesis and prefers a focused product over a generic AI assistant. The best reason to evaluate Consensus is not simply that it uses AI, but that it may align with the roles, systems, and repeatable decisions inside AI research literature software.
- Pilot fit: use Consensus on a real literature search, citation context, and evidence synthesis process with normal and edge-case examples.
- Data fit: confirm what AI research literature software sources Consensus needs and how they are governed.
- User fit: test whether researchers, students, and knowledge workers can understand, edit, and trust Consensus output.
- Commercial fit: ask how Consensus pricing changes as literature search, citation context, and evidence synthesis usage expands.
Visit Consensus official website
Scite: where it may fit best
Scite belongs on the shortlist when your team wants AI support for literature search, citation context, and evidence synthesis and prefers a focused product over a generic AI assistant. The best reason to evaluate Scite is not simply that it uses AI, but that it may align with the roles, systems, and repeatable decisions inside AI research literature software.
- Pilot fit: use Scite on a real literature search, citation context, and evidence synthesis process with normal and edge-case examples.
- Data fit: confirm what AI research literature software sources Scite needs and how they are governed.
- User fit: test whether researchers, students, and knowledge workers can understand, edit, and trust Scite output.
- Commercial fit: ask how Scite pricing changes as literature search, citation context, and evidence synthesis usage expands.
How to choose between the three
The best buying process is to define a narrow workflow, ask each vendor to run the same examples, and compare output quality, implementation time, governance controls, and reporting. For AI research literature software, teams should resist buying the broadest feature list and instead choose the platform that improves the most expensive or repetitive bottleneck.
- Give every vendor the same AI research literature software test cases.
- Score outputs with the researchers, students, and knowledge workers who will actually use the system.
- Ask for AI research literature software security and compliance documentation early.
- Measure before-and-after literature search, citation context, and evidence synthesis time savings, quality, and exception rates.
- Document which AI research literature software decisions remain human-owned.
- Confirm cancellation, expansion, and support terms before signing for Elicit, Consensus, or Scite.
Pricing and ROI questions
Ask Elicit, Consensus, and Scite to separate pilot cost, implementation cost, production cost, and expansion cost. A platform can look affordable during a small AI research literature software test but become hard to justify if pricing grows before workflow value is proven.
Buyer context
A fair comparison of Elicit, Consensus, and Scite starts with the operating problem. For researchers, students, and knowledge workers, the target workflow is literature search, citation context, and evidence synthesis. The winner should be the product that improves that workflow with the least friction, the clearest review process, and the strongest evidence that users will actually adopt it.
These platforms should not be judged only by interface polish or broad AI claims. In AI research literature software, buyers need to test real inputs, edge cases, reporting needs, permission boundaries, and what happens after a recommendation, draft, prediction, or summary is produced.
Evaluation rubric
| Criterion | Elicit | Consensus | Scite |
|---|---|---|---|
| Workflow fit | Test against the highest-volume process. | Check whether the implementation model suits the team. | Validate fit for edge cases and expansion. |
| Data handling | Review source traceability and retention. | Check permissions and data controls. | Confirm imports, exports, and audit logs. |
| Adoption | Ask real users to score output usefulness. | Measure training effort and daily friction. | Track edits, overrides, and support needs. |
| ROI | Measure before-and-after cycle time. | Estimate implementation and admin cost. | Check whether reporting proves value. |
Data, controls, and risk
The data layer matters because AI research literature software may involve workflow data, user activity, documents, messages, product records, and operational context. A strong platform should make it clear how data enters the system, how outputs are created, how permissions work, and how humans can inspect or override results. The most important risk areas are poor source data, weak adoption, unclear ownership, and outputs that are hard to audit.
During a pilot, give all three vendors the same examples and ask them to show source references, confidence boundaries, and exception handling. The goal is not to find the flashiest answer. The goal is to find the most reliable operating process for literature search, citation context, and evidence synthesis.
Implementation differences
Implementation is where the comparison becomes practical. One product may be easier to launch, another may offer deeper configuration, and another may require more services work. For literature search, citation context, and evidence synthesis, the right choice is the one your team can actually operate after onboarding.
- Ask whether integrations for literature search, citation context, and evidence synthesis are native, partner-built, API-based, or services-led.
- Confirm which researchers, students, and knowledge workers roles need training before the first production workflow.
- Decide who owns configuration after the AI research literature software implementation team leaves.
- Check whether AI research literature software reporting can prove time saved, quality improvement, user adoption, exception handling, and measurable workflow throughput to leadership after launch.
- Document what happens when AI research literature software AI output is wrong, incomplete, or disputed.
Best-fit scenarios
Elicit may be the best fit when its strengths line up with the most expensive bottleneck in literature search, citation context, and evidence synthesis. Consensus may be better when implementation style, data controls, or user experience match the buyer's operating model. Scite may be the stronger option when the team values a different balance of automation, oversight, reporting, and rollout support.
A fair comparison of Elicit, Consensus, and Scite should feel like a working session, not a slide deck. Ask each vendor to process the same AI research literature software examples, show the same audit trail, and explain what users do after the AI output appears.
Pricing and commercial checks
Pricing in AI research literature software can depend on seats, usage, volume, modules, implementation services, support tier, data connectors, or enterprise security requirements. A low starting price may not stay low after the first workflow expands. A higher quote may still be reasonable if it reduces manual work, improves quality, and fits governance requirements.
- Ask for AI research literature software pilot pricing and production pricing separately.
- Request a clear definition of usage limits and overage costs for literature search, citation context, and evidence synthesis.
- Confirm whether integrations, onboarding, and support are included for Elicit, Consensus, or Scite.
- Ask how the contract changes if more researchers, students, and knowledge workers teams or workflows are added.
- Tie renewal decisions to measurable AI research literature software outcomes from the pilot.
Recommendation
For most buyers, the safest recommendation is to choose the platform that improves literature search, citation context, and evidence synthesis in a measurable way and gives the team confidence in review, auditability, and exception handling. The best choice may not be the most automated option. It is the option that produces useful output, fits the operating model, and can be governed by the business process owner, an implementation lead, and a reviewer responsible for quality control.
If none of the three tools can prove value with real examples from literature search, citation context, and evidence synthesis, delay the purchase and improve process documentation first. AI software performs best when the team understands data quality, decision rules, and review responsibilities.
Proof to request before purchase
Before choosing between Elicit, Consensus, and Scite, ask for proof that goes beyond sales claims. Each vendor should show a workflow walkthrough, a security or data handling summary, a realistic implementation plan, and examples of how customers measure results. In AI research literature software, a strong proof package should connect product capabilities to literature search, citation context, and evidence synthesis, not just describe generic automation.
- A sample AI research literature software implementation plan with customer responsibilities clearly separated from vendor responsibilities.
- A security and privacy summary for literature search, citation context, and evidence synthesis data processing, retention, access control, and logging.
- A reporting example that shows how researchers, students, and knowledge workers can monitor time saved, quality improvement, user adoption, exception handling, and measurable workflow throughput after literature search, citation context, and evidence synthesis goes live.
- A support model for researchers, students, and knowledge workers that explains what happens after launch, not only during onboarding.
- A pricing model that makes AI research literature software expansion costs visible before the team commits.
What happens after the AI output
The post-output workflow is often where AI research literature software tools succeed or fail. After Elicit, Consensus, or Scite produces a summary, recommendation, draft, alert, prediction, or classification, the team still needs a place to review it, accept it, correct it, route it, and measure the outcome.
During the AI research literature software demo, slow down after the AI output appears. Ask how users correct it, route it, reject it, document it, and report on it. This is where a strong workflow product separates itself from a generic AI wrapper.
Shortlist strategy
Do not try to evaluate every feature at once. Use three gates for this shortlist: workflow fit, governance fit, and economic fit. If a platform fails the workflow gate for literature search, citation context, and evidence synthesis, better reporting will not save it.
| Gate | Pass condition | Decision |
|---|---|---|
| Workflow fit | Improves literature search, citation context, and evidence synthesis with real examples. | Advance to user testing. |
| Governance fit | Controls the main risk areas: poor source data, weak adoption, unclear ownership, and outputs that are hard to audit. | Advance to security and compliance review. |
| Economic fit | Improves time saved, quality improvement, user adoption, exception handling, and measurable workflow throughput enough to justify cost. | Advance to contract negotiation. |
FAQ
Which is the best AI research literature software tool?
There is no universal winner. Elicit, Consensus, and Scite should be compared against your own data, workflows, integrations, and governance requirements.
Should buyers choose the most automated platform?
Not always. In AI research literature software, the safer choice is usually the platform that automates the right parts of literature search, citation context, and evidence synthesis while keeping accountable humans in the loop.
How long should a pilot run?
A useful AI research literature software pilot should include ordinary work, edge cases, user feedback, permission checks, and at least one reporting cycle. For many teams, that means two to six weeks depending on complexity.
Related AI software guides
Use these related guides to compare the same category from another buyer angle.
- Scite Review 2026: AI Research Literature Software
- Consensus Review 2026: AI Research Literature Software
- Elicit Review 2026: AI Research Literature Software
This page is intended to help buyers evaluate AI research literature software options. Current product details, commercial terms, security posture, and compliance documentation should be checked with the vendor before deployment.