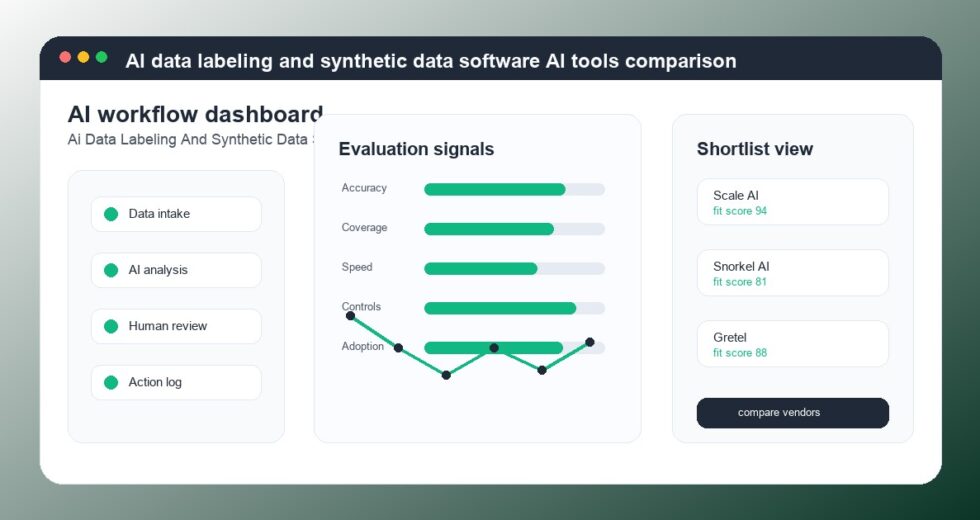
This side-by-side buyer comparison compares Scale AI, Snorkel AI, and Gretel for teams evaluating AI data labeling and synthetic data software. The three tools are not interchangeable. Each may be strong for a different operating model, integration requirement, data maturity level, or rollout style.
For AI, data science, and ML operations teams, the right decision should start with the workflow: training data, labeling, weak supervision, and synthetic data generation. A tool that looks impressive in a demo may be the wrong fit if it cannot connect to existing systems, handle edge cases, or provide the audit trail your team needs.
Short answer
- Choose Scale AI if its workflow depth matches your highest-priority AI data labeling and synthetic data software use case.
- Choose Snorkel AI if its implementation model, integrations, or data approach fits AI, data science, and ML operations teams better.
- Choose Gretel if it offers the strongest match for training data, labeling, weak supervision, and synthetic data generation, rollout needs, or reporting expectations.
- Run a AI data labeling and synthetic data software pilot before making a long-term buying decision.
Comparison table
| Tool | Likely best fit | What to validate | Risk to check |
|---|---|---|---|
| Scale AI | Teams prioritizing training data, labeling, weak supervision, and synthetic data generation | Integration depth and real-case performance | Over-reliance on polished demo examples |
| Snorkel AI | AI, data science, and ML operations teams with specific process constraints | Security, data controls, and workflow ownership | Implementation complexity |
| Gretel | Teams comparing multiple approaches to AI data labeling and synthetic data software | Reporting, user adoption, and support model | Unclear ROI measurement |
Scale AI: where it may fit best
Scale AI belongs on the shortlist when your team wants AI support for training data, labeling, weak supervision, and synthetic data generation and prefers a focused product over a generic AI assistant. The best reason to evaluate Scale AI is not simply that it uses AI, but that it may align with the roles, systems, and repeatable decisions inside AI data labeling and synthetic data software.
- Pilot fit: use Scale AI on a real training data, labeling, weak supervision, and synthetic data generation process with normal and edge-case examples.
- Data fit: confirm what AI data labeling and synthetic data software sources Scale AI needs and how they are governed.
- User fit: test whether AI, data science, and ML operations teams can understand, edit, and trust Scale AI output.
- Commercial fit: ask how Scale AI pricing changes as training data, labeling, weak supervision, and synthetic data generation usage expands.
Visit Scale AI official website
Snorkel AI: where it may fit best
Snorkel AI belongs on the shortlist when your team wants AI support for training data, labeling, weak supervision, and synthetic data generation and prefers a focused product over a generic AI assistant. The best reason to evaluate Snorkel AI is not simply that it uses AI, but that it may align with the roles, systems, and repeatable decisions inside AI data labeling and synthetic data software.
- Pilot fit: use Snorkel AI on a real training data, labeling, weak supervision, and synthetic data generation process with normal and edge-case examples.
- Data fit: confirm what AI data labeling and synthetic data software sources Snorkel AI needs and how they are governed.
- User fit: test whether AI, data science, and ML operations teams can understand, edit, and trust Snorkel AI output.
- Commercial fit: ask how Snorkel AI pricing changes as training data, labeling, weak supervision, and synthetic data generation usage expands.
Visit Snorkel AI official website
Gretel: where it may fit best
Gretel belongs on the shortlist when your team wants AI support for training data, labeling, weak supervision, and synthetic data generation and prefers a focused product over a generic AI assistant. The best reason to evaluate Gretel is not simply that it uses AI, but that it may align with the roles, systems, and repeatable decisions inside AI data labeling and synthetic data software.
- Pilot fit: use Gretel on a real training data, labeling, weak supervision, and synthetic data generation process with normal and edge-case examples.
- Data fit: confirm what AI data labeling and synthetic data software sources Gretel needs and how they are governed.
- User fit: test whether AI, data science, and ML operations teams can understand, edit, and trust Gretel output.
- Commercial fit: ask how Gretel pricing changes as training data, labeling, weak supervision, and synthetic data generation usage expands.
How to choose between the three
The best buying process is to define a narrow workflow, ask each vendor to run the same examples, and compare output quality, implementation time, governance controls, and reporting. For AI data labeling and synthetic data software, teams should resist buying the broadest feature list and instead choose the platform that improves the most expensive or repetitive bottleneck.
- Give every vendor the same AI data labeling and synthetic data software test cases.
- Score outputs with the AI, data science, and ML operations teams who will actually use the system.
- Ask for AI data labeling and synthetic data software security and compliance documentation early.
- Measure before-and-after training data, labeling, weak supervision, and synthetic data generation time savings, quality, and exception rates.
- Document which AI data labeling and synthetic data software decisions remain human-owned.
- Confirm cancellation, expansion, and support terms before signing for Scale AI, Snorkel AI, or Gretel.
Pricing and ROI questions
Buyers should compare price against operating impact, not against AI hype. For AI, data science, and ML operations teams, the right model is the one where cost scales in a way the team can connect to time saved, quality gains, lower exception volume, or better reporting.
Buyer context
A fair comparison of Scale AI, Snorkel AI, and Gretel starts with the operating problem. For AI, data science, and ML operations teams, the target workflow is training data, labeling, weak supervision, and synthetic data generation. The winner should be the product that improves that workflow with the least friction, the clearest review process, and the strongest evidence that users will actually adopt it.
These platforms should not be judged only by interface polish or broad AI claims. In AI data labeling and synthetic data software, buyers need to test real inputs, edge cases, reporting needs, permission boundaries, and what happens after a recommendation, draft, prediction, or summary is produced.
Evaluation rubric
| Criterion | Scale AI | Snorkel AI | Gretel |
|---|---|---|---|
| Workflow fit | Test against the highest-volume process. | Check whether the implementation model suits the team. | Validate fit for edge cases and expansion. |
| Data handling | Review source traceability and retention. | Check permissions and data controls. | Confirm imports, exports, and audit logs. |
| Adoption | Ask real users to score output usefulness. | Measure training effort and daily friction. | Track edits, overrides, and support needs. |
| ROI | Measure before-and-after cycle time. | Estimate implementation and admin cost. | Check whether reporting proves value. |
Data, controls, and risk
The data layer matters because AI data labeling and synthetic data software may involve workflow data, user activity, documents, messages, product records, and operational context. A strong platform should make it clear how data enters the system, how outputs are created, how permissions work, and how humans can inspect or override results. The most important risk areas are poor source data, weak adoption, unclear ownership, and outputs that are hard to audit.
During a pilot, give all three vendors the same examples and ask them to show source references, confidence boundaries, and exception handling. The goal is not to find the flashiest answer. The goal is to find the most reliable operating process for training data, labeling, weak supervision, and synthetic data generation.
Implementation differences
Scale AI, Snorkel AI, and Gretel may require different levels of configuration, integration, training, and change management. Buyers should ask each vendor for a realistic plan covering timeline, customer responsibilities, admin setup, security review, and the handoff from pilot to production.
- Ask whether integrations for training data, labeling, weak supervision, and synthetic data generation are native, partner-built, API-based, or services-led.
- Confirm which AI, data science, and ML operations teams roles need training before the first production workflow.
- Decide who owns configuration after the AI data labeling and synthetic data software implementation team leaves.
- Check whether AI data labeling and synthetic data software reporting can prove time saved, quality improvement, user adoption, exception handling, and measurable workflow throughput to leadership after launch.
- Document what happens when AI data labeling and synthetic data software AI output is wrong, incomplete, or disputed.
Best-fit scenarios
Scale AI may be the best fit when its strengths line up with the most expensive bottleneck in training data, labeling, weak supervision, and synthetic data generation. Snorkel AI may be better when implementation style, data controls, or user experience match the buyer's operating model. Gretel may be the stronger option when the team values a different balance of automation, oversight, reporting, and rollout support.
Use a shared test set instead of three separate vendor demos. The same ordinary cases, difficult cases, and incomplete inputs should be used for Scale AI, Snorkel AI, and Gretel so the team can compare evidence rather than presentation style.
Pricing and commercial checks
Pricing in AI data labeling and synthetic data software can depend on seats, usage, volume, modules, implementation services, support tier, data connectors, or enterprise security requirements. A low starting price may not stay low after the first workflow expands. A higher quote may still be reasonable if it reduces manual work, improves quality, and fits governance requirements.
- Ask for AI data labeling and synthetic data software pilot pricing and production pricing separately.
- Request a clear definition of usage limits and overage costs for training data, labeling, weak supervision, and synthetic data generation.
- Confirm whether integrations, onboarding, and support are included for Scale AI, Snorkel AI, or Gretel.
- Ask how the contract changes if more AI, data science, and ML operations teams teams or workflows are added.
- Tie renewal decisions to measurable AI data labeling and synthetic data software outcomes from the pilot.
Recommendation
For most buyers, the safest recommendation is to choose the platform that improves training data, labeling, weak supervision, and synthetic data generation in a measurable way and gives the team confidence in review, auditability, and exception handling. The best choice may not be the most automated option. It is the option that produces useful output, fits the operating model, and can be governed by the business process owner, an implementation lead, and a reviewer responsible for quality control.
If every option feels vague after testing training data, labeling, weak supervision, and synthetic data generation, the problem may be readiness rather than vendor quality. In that case, improve the AI data labeling and synthetic data software operating model before adding another AI layer.
Proof to request before purchase
Before choosing between Scale AI, Snorkel AI, and Gretel, ask for proof that goes beyond sales claims. Each vendor should show a workflow walkthrough, a security or data handling summary, a realistic implementation plan, and examples of how customers measure results. In AI data labeling and synthetic data software, a strong proof package should connect product capabilities to training data, labeling, weak supervision, and synthetic data generation, not just describe generic automation.
- A sample AI data labeling and synthetic data software implementation plan with customer responsibilities clearly separated from vendor responsibilities.
- A security and privacy summary for training data, labeling, weak supervision, and synthetic data generation data processing, retention, access control, and logging.
- A reporting example that shows how AI, data science, and ML operations teams can monitor time saved, quality improvement, user adoption, exception handling, and measurable workflow throughput after training data, labeling, weak supervision, and synthetic data generation goes live.
- A support model for AI, data science, and ML operations teams that explains what happens after launch, not only during onboarding.
- A pricing model that makes AI data labeling and synthetic data software expansion costs visible before the team commits.
What happens after the AI output
A polished AI answer can still create operational debt if nobody knows what happens next. Each vendor should show the AI data labeling and synthetic data software path from input to output to human decision to final record.
Ask each vendor who sees the training data, labeling, weak supervision, and synthetic data generation output first, whether edits are saved, how managers audit decisions later, and whether corrections improve future workflows. These questions are often more important than broad claims about model intelligence.
Shortlist strategy
For AI, data science, and ML operations teams, the shortlist should move from practical to commercial: can the tool work, can the team control it, and can the business justify it after the first pilot?
| Gate | Pass condition | Decision |
|---|---|---|
| Workflow fit | Improves training data, labeling, weak supervision, and synthetic data generation with real examples. | Advance to user testing. |
| Governance fit | Controls the main risk areas: poor source data, weak adoption, unclear ownership, and outputs that are hard to audit. | Advance to security and compliance review. |
| Economic fit | Improves time saved, quality improvement, user adoption, exception handling, and measurable workflow throughput enough to justify cost. | Advance to contract negotiation. |
FAQ
Which is the best AI data labeling and synthetic data software tool?
There is no universal winner. Scale AI, Snorkel AI, and Gretel should be compared against your own data, workflows, integrations, and governance requirements.
Should buyers choose the most automated platform?
The most automated product is not automatically the best fit. Buyers should prefer the option that balances speed, traceability, user control, and measurable AI data labeling and synthetic data software outcomes.
How long should a pilot run?
The pilot should last until AI, data science, and ML operations teams can compare before-and-after results with confidence. In practice, that usually means several weeks of real examples, user feedback, and governance review.
Related AI software guides
Use these related guides to compare the same category from another buyer angle.
- Best AI Data Labeling and Synthetic Data Tools 2026
- Gretel Review 2026: AI Data Labeling and Synthetic Data Software
- Snorkel AI Review 2026: AI Data Labeling and Synthetic Data
- Scale AI Review 2026: AI Data Labeling and Synthetic Data
This article is a software evaluation guide, not a vendor endorsement. Buyers should verify current AI data labeling and synthetic data software features, pricing, integrations, compliance claims, and support terms directly with the vendor.